
15x
Tok/$ vs NVIDIA Rubin
6x
Tok/W for low-latency 1T+ MoEs
>30x
lower latency for large-model inference

We ship on proven compute IP.
The first product leverages existing and silicon-proven compute engine IP licensed from external parties. The risk lives in the photonic interconnect — which we've developed for 4+ years.
Memory Capacity
10 TB
Memory bandwidth
240 TB/s
Power envelope
20kW
Off-wafer IO bandwidth
10 TB/s
Form factor
15U
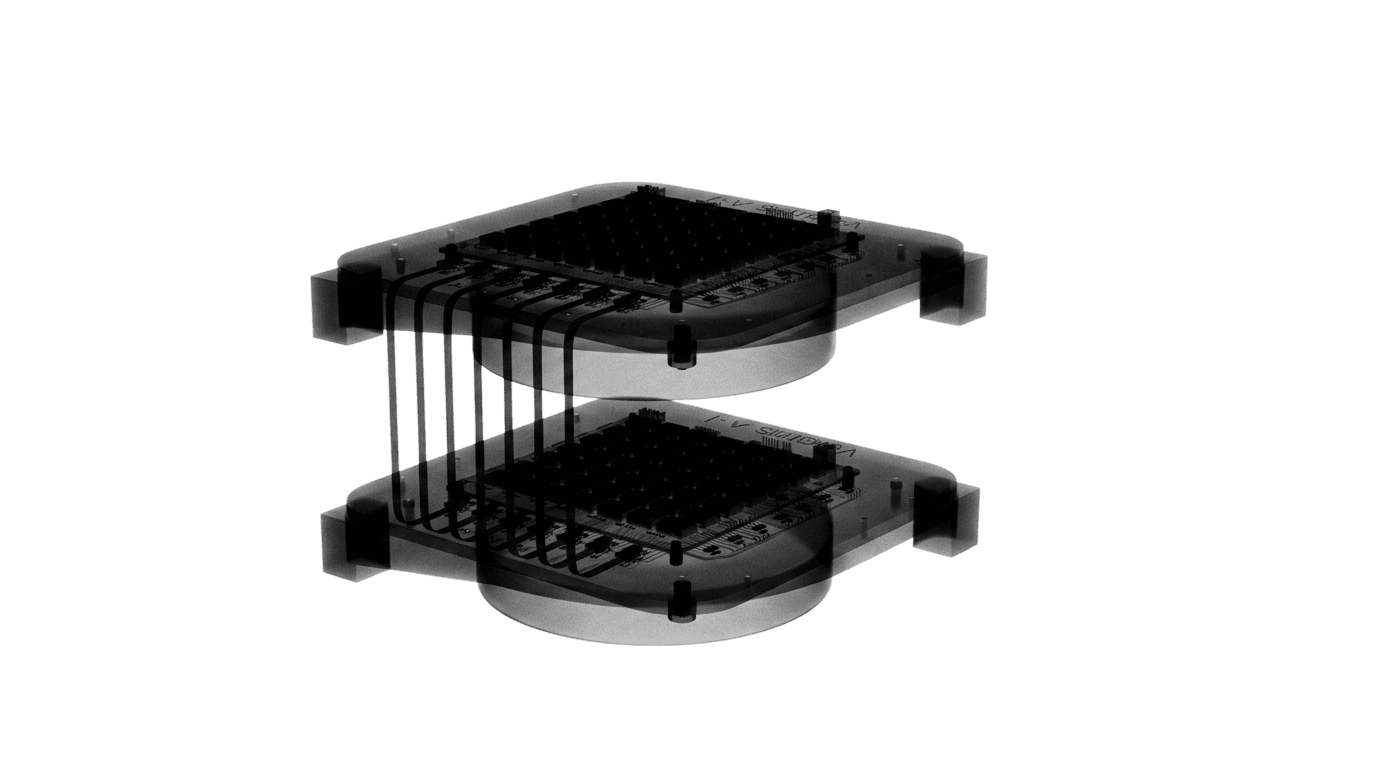
15x Tok/$ and 6x Tok/W changes your unit economics.
Get low latency tokens, for the largest models and context lengths, while also reducing TCO.
